On-Premise LLM Deployment in the USA
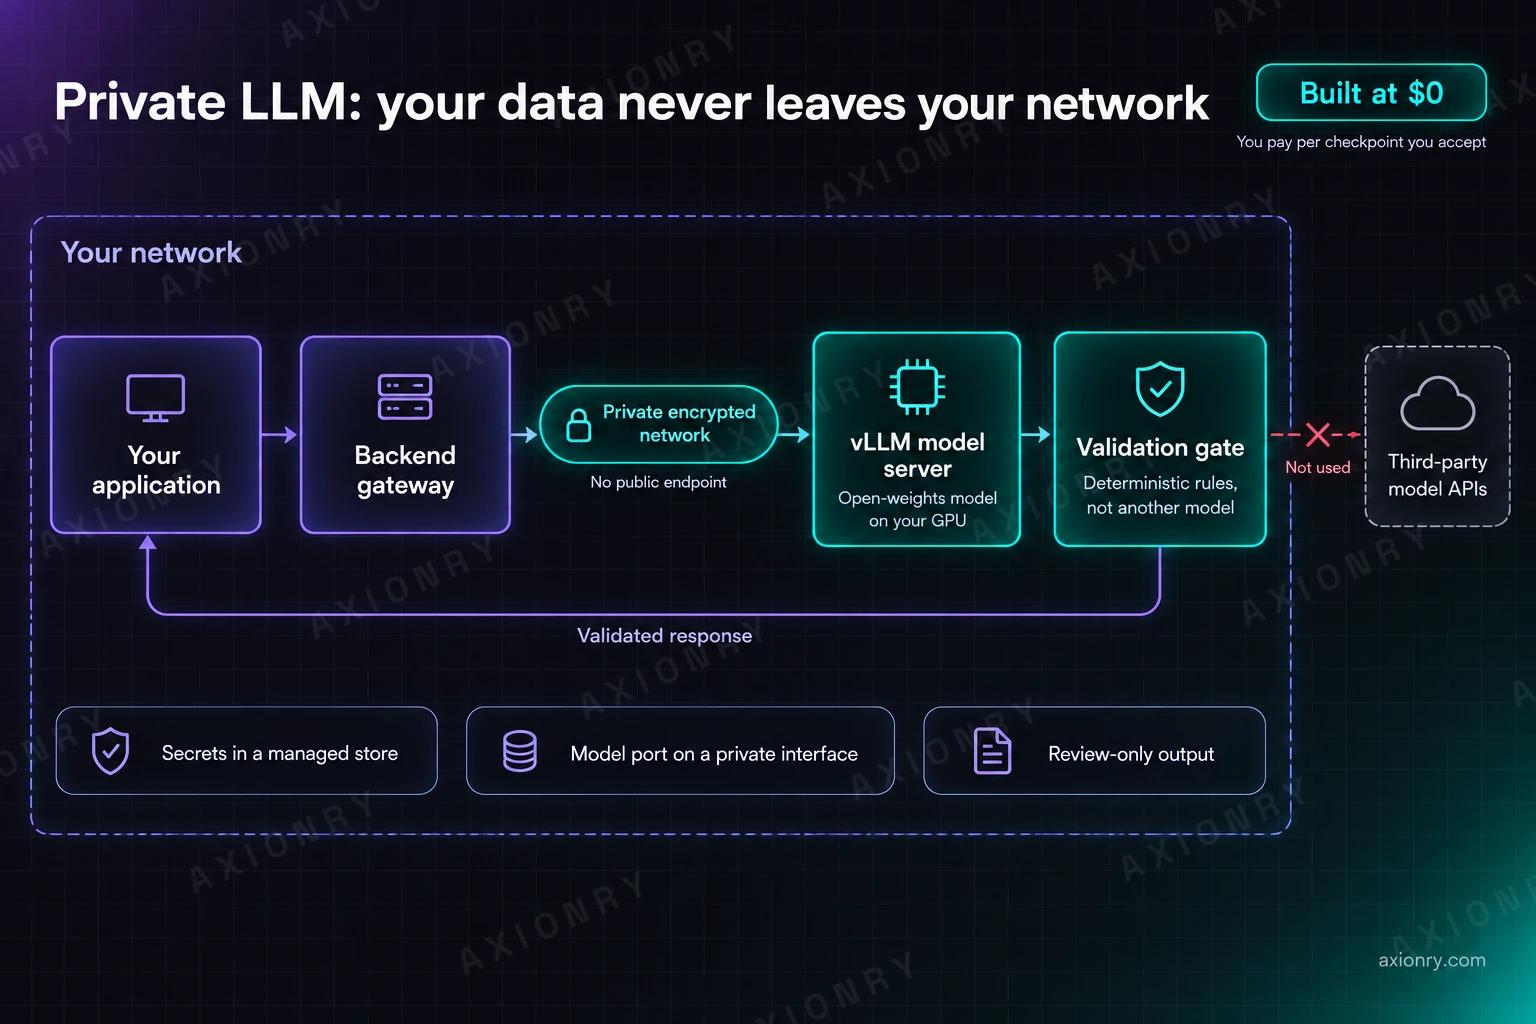
You have the GPU and you have the model. What is missing is the leg in between: the model exposed as a reliable private API, reached securely from your application, returning data you can trust. That is the whole engagement.
The US is where AI budgets are largest and engineering rates are highest, which is exactly why so much of this work is quoted at numbers that have little to do with the effort involved. An agency will price a production MVP in the mid five figures and staff it with three people who have shipped less than the one you actually wanted. The gap between what a build costs and what it is billed at is the whole reason this arrangement works.
What you get
- vLLM serving tuned to your GPU: quantisation on the native kernel path, KV cache sizing, continuous batching, prefix caching
- A private network path with no public exposure, verified as a direct peer connection rather than a relay
- Schema-constrained responses plus a deterministic QA gate, so a wrong answer is rejected rather than rendered
- Documented baseline: tokens per second, time to first token, real concurrent capacity
- Infrastructure as code in your repository, a runbook, and every credential held by you
No upfront payment and no escrow required. You hold every dollar until a checkpoint is delivered and accepted, and thirty days of defect correction is included. Scope and price are set on a call.
Invoiced in USD, payable by Wise or bank transfer.
Request a callback
You speak to the engineer who does the work. No sales rep, no deck.
Get it built at $0.
That is not a discount. It is when you pay. The work is split into checkpoints with acceptance criteria written down before anything starts, and each checkpoint is invoiced only after you have seen it and accepted it. No deposit.
- $0 to start
- You hold every dollar until a checkpoint is delivered and you accept it. No approval, no invoice.
- Fixed cost, unlimited features
- Or hire the team outright: one fixed monthly cost, unlimited feature development, any stack.
- The engineer takes your call
- The person on your first call is the one who architects and writes it. No account managers, no bench time.
A US agency quotes $50,000 to $150,000 for the same build and asks for 40 to 50% of it before a line is written. Account managers, project managers, sales commission and bench time. None of it appears in your product.
Three stages, nothing hidden.
Fixed-fee assessment
Five business days from the day access is in place. Your stack examined end to end, existing work classified as preserved or replaced with reasons, the connection design, and acceptance criteria written as testable statements.
Implementation in checkpoints
Around three weeks. Each checkpoint has written acceptance criteria agreed before work starts, and is invoiced only after you accept it. Appoint an independent technical reviewer if you want one.
Handover and closeout
One real request through your real application, on synthetic data, passing every QA rule. Runbook, recorded handoff, and all our access removed with written confirmation.
What actually applies here.
Regulation and data
The pressure almost never comes from a regulator directly. It comes from your own customers. Enterprise buyers now run security reviews that ask where inference happens and who can read the prompt, and healthcare and financial clients increasingly write data-handling terms into contracts that a shared model API cannot satisfy. When that happens, moving inference inside infrastructure you control is usually the shortest path to a signed deal rather than a technical preference.
Contracting and payment
You contract with an individual consultant based in India rather than a US entity. Invoices are issued in USD and paid by Wise or bank transfer, with no payroll and no benefits load on your side. Whatever documentation your finance team or counsel needs from an overseas contractor is provided before work starts.
Working hours
Four or more hours of daily overlap with US Eastern, calls scheduled in your morning, and same-day replies on working days.
Do you work with US companies from India?
Yes, and most engagements are with US companies. You contract with an individual consultant, invoiced in USD, with any documentation your finance team needs provided up front. No US entity, no payroll, no benefits overhead on your side.
How do you handle the time difference with US teams?
Four or more hours of daily overlap with US Eastern, calls in your morning, and same-day responses on working days. Work needing review is handed over at the end of your day and waiting when you start the next one.
How do you handle access to our systems?
Accounts stay yours throughout. Access is named and limited-privilege, work runs on synthetic data where possible, code and configuration are delivered continuously into your repository, and all access is removed at handover with written confirmation.
We already have hardware and a model running. Is that a problem?
It is the ideal starting point. Existing work is classified during the assessment as preserved unchanged, preserved with changes, or replaced, with reasons, and nothing is replaced without your written agreement.
Can it be fully air gapped?
Yes, including model and dependency mirroring, offline updates and local evaluation, with no outbound network access at all.
Who holds the accounts?
You do, throughout. Cloud accounts are created and held by you, our access is named and limited-privilege, and it is removed at handover with written confirmation.