On-Premise LLM Deployment in Waterloo
The best On-Premise LLM Deployment in Waterloo, at the best available price.
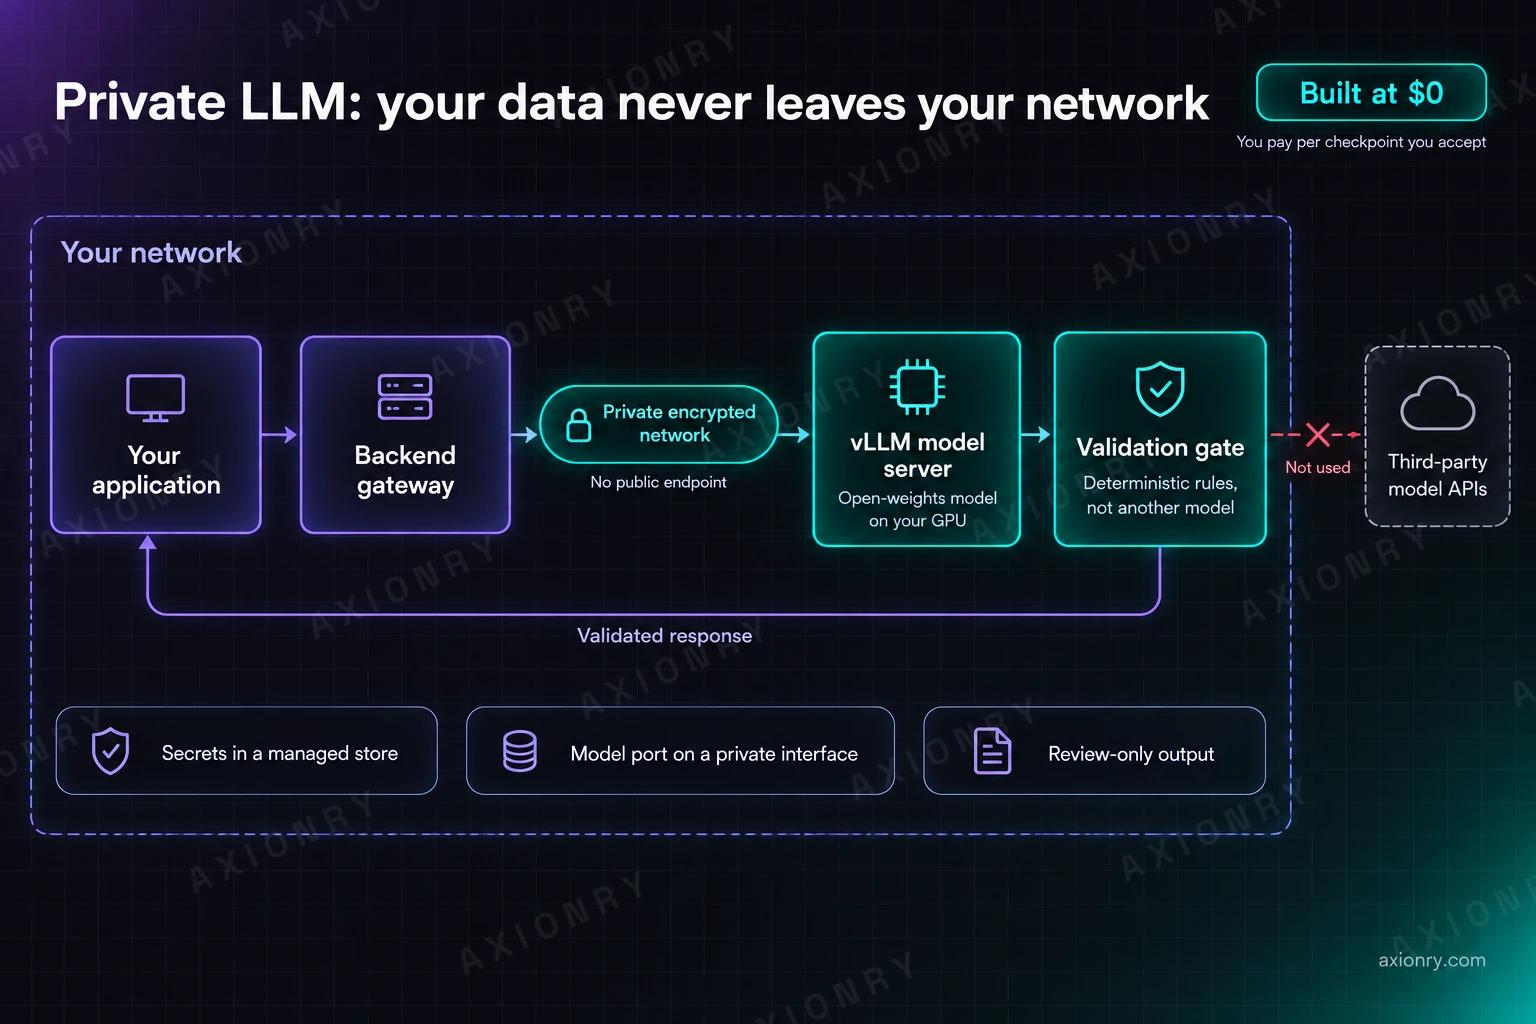
You have the GPU and you have the model. What is missing is the leg in between: the model exposed as a reliable private API, reached securely from your application, returning data you can trust. That is the whole engagement.
Waterloo Region, with Kitchener, punches well above its size in technology, driven by the University of Waterloo's co-op engineering programme, Communitech and a long line of startups. Founders here are often technical, and the gap is more often production and product experience than coding skill.
Waterloo's insurers, and the startups selling to them, deal with policyholder data that cannot go to a shared API. A private deployment in a Canadian region keeps it under your control.
What you get
- vLLM serving tuned to your GPU: quantisation on the native kernel path, KV cache sizing, continuous batching, prefix caching
- A private network path with no public exposure, verified as a direct peer connection rather than a relay
- Schema-constrained responses plus a deterministic QA gate, so a wrong answer is rejected rather than rendered
- Documented baseline: tokens per second, time to first token, real concurrent capacity
- Infrastructure as code in your repository, a runbook, and every credential held by you
No upfront payment and no escrow required. You hold every dollar until a checkpoint is delivered and accepted, and thirty days of defect correction is included. Scope and price are set on a call.
Invoiced in USD or CAD, payable by Wise or bank transfer.
Request a callback
You speak to the engineer who does the work. No sales rep, no deck.
Who builds here
AI Product & MVP Development
Waterloo founders are usually technical and fast, and what helps most is a senior engineer who has shipped production products, to get the first version live and stable.
What Waterloo companies build with us
Get it built at $0.
That is not a discount. It is when you pay. The work is split into checkpoints with acceptance criteria written down before anything starts, and each checkpoint is invoiced only after you have seen it and accepted it. No deposit.
- $0 to start
- You hold every dollar until a checkpoint is delivered and you accept it. No approval, no invoice.
- Fixed cost, unlimited features
- Or hire the team outright: one fixed monthly cost, unlimited feature development, any stack.
- The engineer takes your call
- The person on your first call is the one who architects and writes it. No account managers, no bench time.
A US agency quotes $50,000 to $150,000 for the same build and asks for 40 to 50% of it before a line is written. Account managers, project managers, sales commission and bench time. None of it appears in your product.
Three stages, nothing hidden.
Fixed-fee assessment
Five business days from the day access is in place. Your stack examined end to end, existing work classified as preserved or replaced with reasons, the connection design, and acceptance criteria written as testable statements.
Implementation in checkpoints
Around three weeks. Each checkpoint has written acceptance criteria agreed before work starts, and is invoiced only after you accept it. Appoint an independent technical reviewer if you want one.
Handover and closeout
One real request through your real application, on synthetic data, passing every QA rule. Runbook, recorded handoff, and all our access removed with written confirmation.
What actually applies here.
Regulation and data
Private companies in Ontario are covered by PIPEDA, and the region's insurers are supervised by OSFI or Ontario's financial regulator, which shapes how their vendors handle data. Ontario now requires employers to disclose in public job postings if AI is used to screen or assess applicants. Canada has no federal AI law yet, after the proposed AIDA died in 2025, but enterprise buyers ask about AI governance anyway.
Contracting and payment
You contract with an individual consultant based in India. Invoices in CAD or USD, paid by Wise or bank transfer. Your accountant treats an overseas supplier in the usual way, and any paperwork they need is provided before work starts.
Working hours
Four or more hours of daily overlap with Eastern time, calls in your morning, and same-day replies on working days.
Can you work alongside co-op students?
Yes. A senior engineer can set the architecture and review their work, so each co-op term produces code that stays useful after it ends.
Do you work with Kitchener companies too?
Yes, anywhere in Waterloo Region. The work is remote with calls in your morning Eastern time.
We already have hardware and a model running. Is that a problem?
It is the ideal starting point. Existing work is classified during the assessment as preserved unchanged, preserved with changes, or replaced, with reasons, and nothing is replaced without your written agreement.
Can it be fully air gapped?
Yes, including model and dependency mirroring, offline updates and local evaluation, with no outbound network access at all.
Who holds the accounts?
You do, throughout. Cloud accounts are created and held by you, our access is named and limited-privilege, and it is removed at handover with written confirmation.
Private LLM Infrastructure
Self-hosted LLM deployment on hardware you own. vLLM serving, private networking, validated output.