AI Data Analyst in Bengaluru
The best AI Data Analyst in Bengaluru, at the best available price.
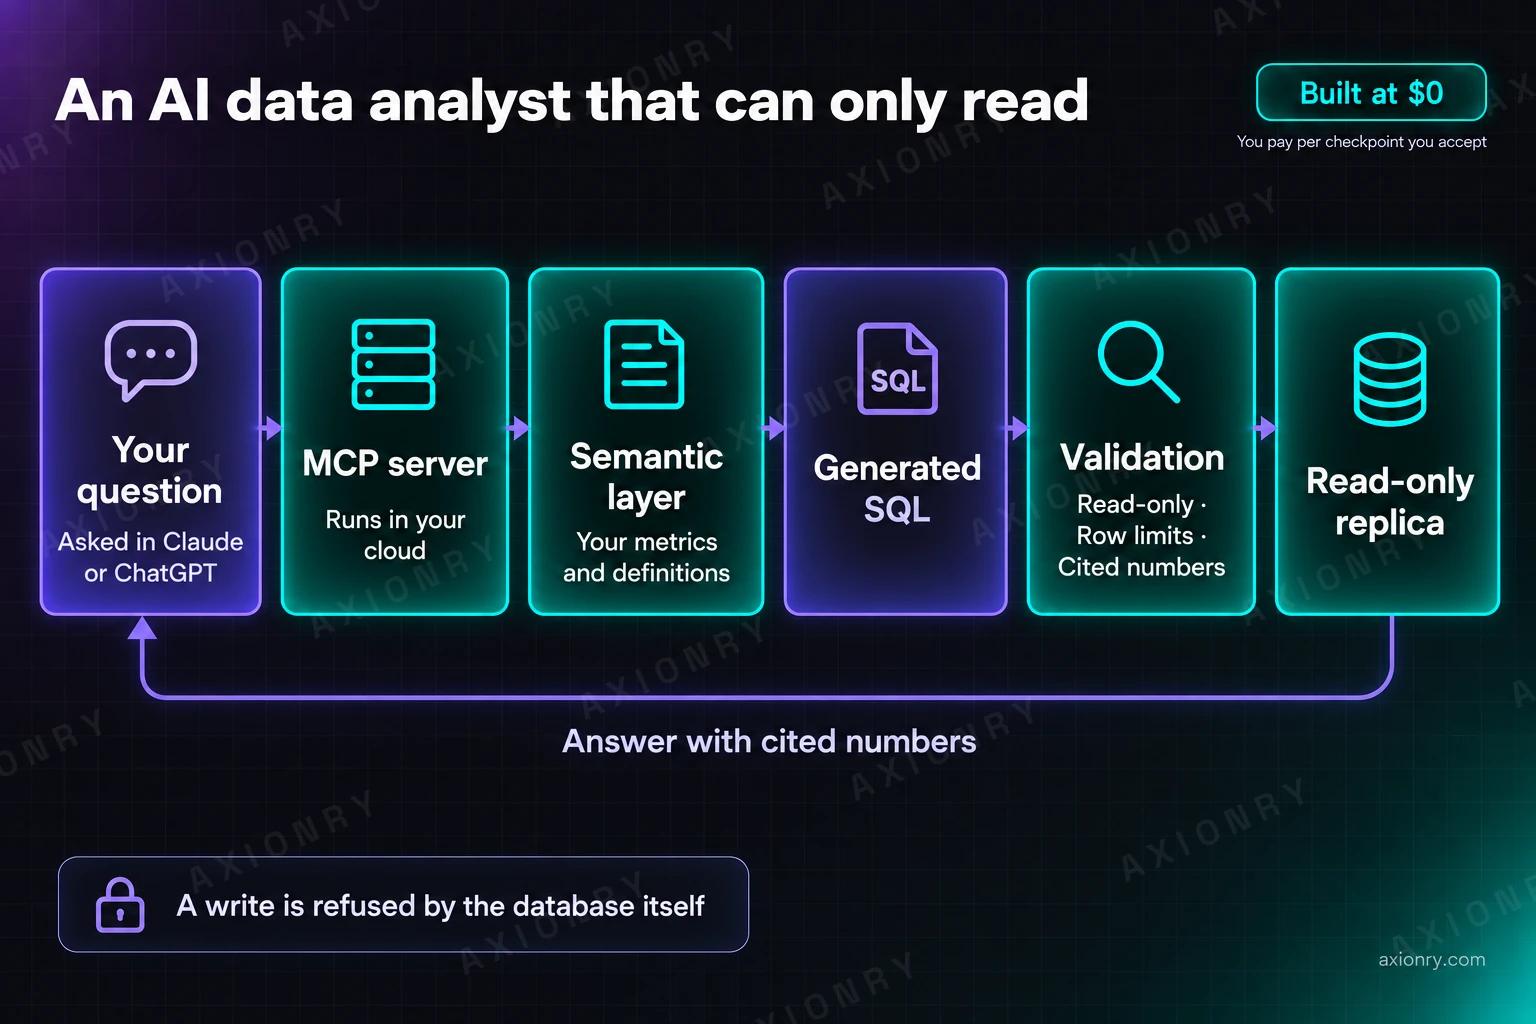
Your team asks in English. The service finds the tables, writes the SQL, runs it against a read-only replica inside your own cloud, and returns the number with the query attached. It cannot touch a table whose schema it has not just read, and that is enforced in code rather than requested in a prompt. Starts at $0: you pay at checkpoints you accept.
Bengaluru is where India's product companies, venture-funded startups and the engineering centres of global firms sit side by side, so the person buying is usually an engineer. Buyers judge a supplier on the code, the architecture and how quickly questions get answered, and they weigh any outside help against the time it takes to hire into a market where engineers with production AI experience are heavily contested.
Companies here usually already run a warehouse such as BigQuery, Snowflake or a Postgres replica, and a small data team buried in requests from product and growth. A read-only analyst that writes the SQL and shows it lets those teams answer routine questions themselves.
What you get
- Deployed in your own cloud account against a read-only replica you create, so we never hold a credential to your database
- A signed schema check the model cannot skip: no SQL runs against a table it has not just inspected, and the tokens expire in fifteen minutes
- A grant list your data owner approves, naming the exact tables and columns the analyst may read, with everything else refused at the database
- Exposed inside Claude or ChatGPT in your organisation's workspace, behind your existing Google sign in, so nobody learns a new interface
- Every question logged with the SQL it ran, the tables it touched and whether it errored, which is what an auditor actually asks for
- Runs on a private LLM on your own hardware where data security demands it, up to fully air-gapped, so nothing at all crosses your perimeter
No payment before a checkpoint is delivered and accepted. Most builds land between $6,000 and $18,000 depending on how many databases are in scope and how much of the schema the first domain covers. Optional upkeep from $1,200 a month, and only if you want it.
Invoiced in INR, with GST as applicable.
Request a callback
You speak to the engineer who does the work. No sales rep, no deck.
Who builds here
AI Development Company
Most Bengaluru companies already have capable engineers. What they usually lack is someone who has shipped retrieval, agents or voice to production and kept them working, so a scoped AI engagement inside the existing team is the most useful place to start.
How many free signups from June converted to paid, by week?
customersplan tier is a column here, not a separate status table
subscriptionsone row per plan change, so take the first paid one
AQIAaPr2xQAAAACqL3d1ZwSELECT DATE_TRUNC('week', s."startedAt")
AS "Week",
COUNT(DISTINCT c.id) AS "Converted"
FROM customers c
JOIN subscriptions s
ON s."customerId" = c.id
WHERE c.plan = 'free'
AND s.plan = 'paid'
AND c."createdAt" >= DATE '2026-06-01'
AND c."createdAt" < DATE '2026-07-01'
GROUP BY 1 ORDER BY 1| Week | Converted |
|---|---|
| 2026-06-01 | 214 |
| 2026-06-08 | 188 |
| 2026-06-15 | 243 |
| 2026-06-22 | 201 |
Stage three refuses to run unless it is handed a valid token from stage two for a table in the query. The model cannot skip the schema read, because the check is a signature in code rather than an instruction in a prompt.
What Bengaluru companies build with us
Get it built at $0.
That is not a discount. It is when you pay. The work is split into checkpoints with acceptance criteria written down before anything starts, and each checkpoint is invoiced only after you have seen it and accepted it. No deposit.
- $0 to start
- You hold every dollar until a checkpoint is delivered and you accept it. No approval, no invoice.
- Fixed cost, unlimited features
- Or hire the team outright: one fixed monthly cost, unlimited feature development, any stack.
- The engineer takes your call
- The person on your first call is the one who architects and writes it. No account managers, no bench time.
A US agency quotes $50,000 to $150,000 for the same build and asks for 40 to 50% of it before a line is written. Account managers, project managers, sales commission and bench time. None of it appears in your product.
Three stages, nothing hidden.
Fixed-fee assessment
Five business days from the day read-only access is in place. Schema inventoried, the questions your team actually asks classified as answerable or not, the grant list drafted with whoever owns data protection, and acceptance criteria written as testable statements.
Build in checkpoints
About three weeks. Deployed in your cloud account, connected to your replica and to your assistant workspace, with the semantic layer written for the first domain. Each checkpoint has criteria agreed before work starts and is invoiced only once you accept it.
Handover and closeout
A real question from your team, answered end to end, with the SQL shown and the numbers reconciled against the source rows. Runbook, recorded handoff, code and semantic layer in your repository, and all our access removed with written confirmation.
What actually applies here.
Regulation and data
The DPDP Act 2023 governs personal data, and the DPDP Rules notified in November 2025 phase in over eighteen months, so SaaS companies here selling to Indian enterprises are already being asked about consent, retention and breach handling. Karnataka's GCC Policy 2024-29 and the state IT policy for 2025-30, approved by the cabinet in November 2025, steer incentives towards R&D, skilling and locations beyond Bengaluru; they are incentive schemes and set no data rules of their own. The Karnataka Data Centre Policy 2022-27 is under review, with the state signalling that new facilities should be sited outside the city. Health tech teams building diagnostic software should check whether CDSCO's medical device rules apply to them.
Contracting and payment
Simple domestic contracting. Invoices in INR with GST as applicable, under a standard services agreement. No cross-border payment friction, no forex conversion cost, and no time spent on paperwork for an overseas supplier.
Working hours
Same time zone. I work from India on IST, so calls, reviews and replies all happen inside your normal working day.
We already have an engineering team in Bengaluru. Where do you fit?
Usually alongside them, on the part they have not done before: model serving, retrieval, agents or voice. The work happens in your repository and through your review process, and handover includes the evaluation sets and runbooks your engineers need to own it afterwards.
Are the Karnataka GCC and IT policies relevant to working with you?
Not directly. Those policies offer incentives for companies setting up or expanding in the state, mainly for R&D, skilling and locations beyond Bengaluru. Whether a particular engagement or hire counts towards a claim is a question for your own advisers, and we do not advise on incentive applications.
Do we need to meet in person?
No. The work is remote and on IST, so calls and code reviews happen inside your normal working day. Decisions, documentation and the recorded handover are written so that anyone on your team can follow what was built without a meeting.
We already have a BI tool. Does this replace it?
No, and it should not. Your dashboards answer the questions somebody anticipated, and they will keep doing that. This answers the ones nobody built a chart for, which is where the waiting happens. Teams that keep both end up using the dashboards for the standing numbers and the analyst for everything else.
How long before somebody can ask a real question?
Usually inside the first week of the build, on a narrow slice of the schema. The first domain being useful early is the point of doing it in checkpoints: you see it working on your own data before most of the money is committed.
What if our schema is a mess?
Most are, and it changes the shape of the work rather than ruling it out. Undocumented columns, legacy tables nobody dares delete and two spellings of the same idea are normal. The assessment tells you plainly how much of that has to be untangled first, and if the answer is that you need a data cleanup before an analyst is worth building, you will be told that instead of sold this.
AI Data Analyst
An AI data analyst on your own read-only replica. Natural language to SQL that cannot query a table it has not read.